-
This paper was submitted to arXiv on June 17, 2021. It proposes a method called **Low-Rank Adaptation, or LoRA, that reduces the number of trainable parameters for downstream tasks in natural language processing. LoRA injects trainable rank decomposition matrices into each layer of the Transformer architecture, which greatly reduces the number of trainable parameters. LoRA performs on-par or better than fine-tuning in model quality on RoBERTa, DeBERTa, GPT-2, and GPT-3, despite having fewer trainable parameters, a higher training throughput, and, unlike adapters, no additional inference latency (time to output). It also works for image diffusion.
-
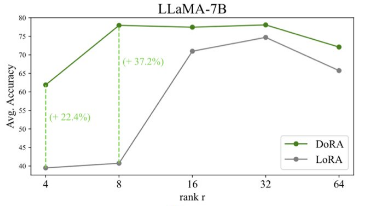
Introducing DoRA, a High-Performing Alternative to LoRA for Fine-Tuning | NVIDIA Technical Blog
-
catid/dora: Implementation of DoRA (github.com) new kid?
-
[2106.09685] LoRA: Low-Rank Adaptation of Large Language Models (arxiv.org)
-
Huggingface Large language models LoRA DoRA etc and LoRA DoRA etc can be found with a simply filter.
- [Models